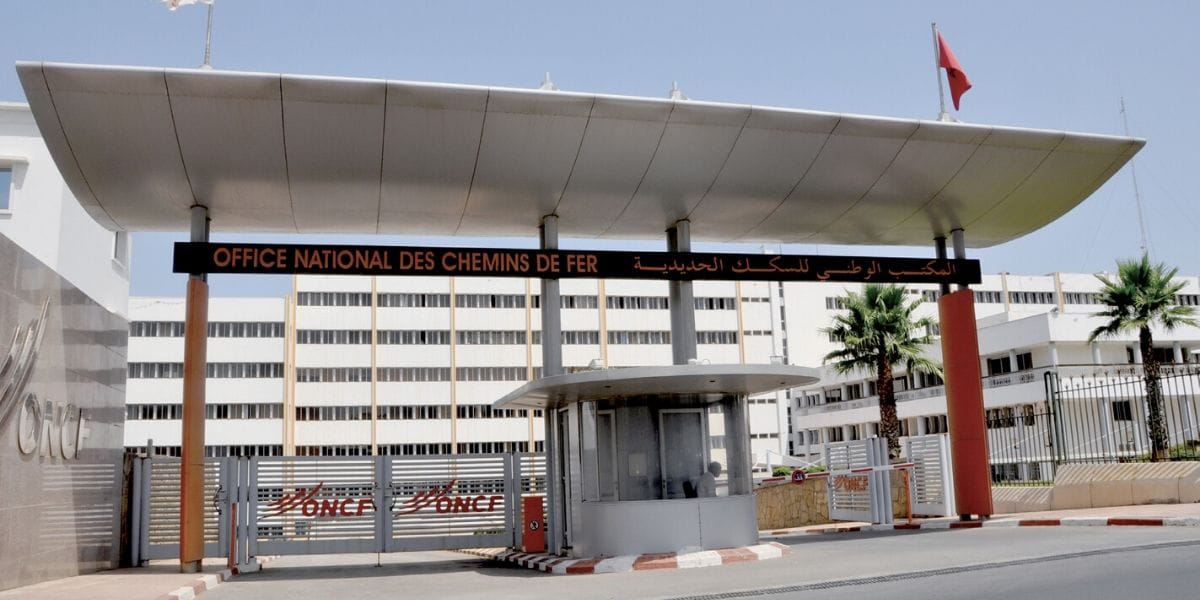
For three months this summer I worked at ONCF, Morocco’s national railway operator, inside the Data & Décisionnel service. The brief was one sentence long.
“Automatically recommend the best trip to travellers, based on their preferences, constraints and behaviour, across the digital sales channels.”
What follows is what that sentence actually turned into, including the part where my model scored 0.126 AUC against 0.5 for random ranking, and never raised a single error while doing it.
The problem nobody writes on the brief
Recommender tutorials start with MovieLens: a tidy matrix of users, items and star ratings. This problem differed in three ways that shaped everything downstream.
Nobody rates a train ticket. All you have is that someone bought one — implicit feedback. A zero in the matrix doesn’t mean “disliked”, it means “never bought”, which mixes genuine disinterest with simple non-exposure. Hu, Koren and Volinsky’s 2008 paper splits that signal into a binary preference and a confidence weight, and that framing is what makes ALS applicable at all.
Most travellers have almost no history. On the data I received, 76.5% of travellers had fewer than three recorded purchases and 50.9% had exactly one. Cold start wasn’t an edge case to handle politely; it was the majority of traffic.
Retraining per login is not an option. The design splits the cost in two: route factors are refreshed by a nightly batch, and a traveller’s own vector is recomputed at login by folding-in, projecting one user’s interactions against already-trained item factors. Yesterday’s price for the routes, this second’s price for the traveller.
The data was not what anyone expected
The plan was a live pyodbc connection to the SQL Server warehouse. What arrived instead were three CSV exports, in three different formats, covering three disjoint time windows.
- test.csv — 946,155 rows, with header, Dec 2017 to Mar 2020
- test1.csv — 1,000,000 rows, with header, 2021
- test2.csv — 445,646 rows, no header row at all, 2023
That last one is the interesting one: fifteen columns with nothing but positions. The tempting assumption is that they are the first fifteen columns of the other file, in order. That assumption is falsifiable, and it was false — at position 3 one file holds a categorical taking only {1, 2} while the other holds a nine-digit integer that is almost always unique.
So instead of matching by position, I matched by statistical fingerprint, comparing value ranges, cardinality and repetition rates across a 200,000-row sample of each file. One column took only {1, −1, 0} — unmistakably the signed sale/cancellation ledger. Two had compatible but non-discriminating fingerprints, and were flagged as medium confidence everywhere they were used. One had no plausible counterpart at all, and kept an explicit “no known equivalent” name rather than being forced onto something it probably wasn’t.
That last decision felt pedantic at the time. It wasn’t. The two medium-confidence columns came back later as the measurable source of noise in the model. Labelling uncertainty paid off.
Cleaning, in an order that isn’t interchangeable
The quantity column is a signed ledger, not a count: +1 is a sale, −1 cancels a previous one, and a cancellation row is identical to the sale it cancels on every other column. Cleaning ran in three passes per source, before merging. Match sales to cancellations and drop both, comparing price and quantity in absolute value so (+1, 131) and (−1, −131) hash to the same key. Then drop exact duplicates, which are extraction artefacts. Then drop rows with no client or no route, because they can’t be placed in a user × item matrix.
The order matters, and not in an obvious way. Deduplicating first would collapse a (+1, +1, −1) group into one +1 and one −1, which then cancel each other and destroy a real sale. Pairing has to happen while the multiplicity is still there.
- test.csv: 946,155 → 880,371 rows, 31,982 pairs removed, 0.2% residual duplicates
- test1.csv: 1,000,000 → 902,554 rows, 23,341 pairs removed, 5.0% duplicates
- test2.csv: 445,646 → 350,658 rows, 18,615 pairs removed, 12.5% duplicates
A duplicate rate spanning 0.2% to 12.5% is a real signal about the export processes. Clean after merging and it averages into a single meaningless number.
The matrix that crashed the machine
666,858 travellers × 1,736 routes in float64 is about 9.3 GB. I know, because the first version built it densely and died of an out-of-memory error on the first real run. Built sparsely, only the observed triples are stored: 1,186,284 of them, a matrix 99.9% empty and 21.8 MB on disk.
def build_user_item_matrix(raw_frame: pd.DataFrame) -> InteractionMatrix:
    raw_frame = raw_frame.dropna(subset=[USER_COL, ITEM_COL])
    users = raw_frame[USER_COL].astype("category")
    items = raw_frame[ITEM_COL].astype("category")
    # coo_matrix sums duplicate (row, col) entries on conversion to csr,
    # which nets the signed sale/cancellation events automatically.
    coo = coo_matrix((raw_frame[VALUE_COL], (users.cat.codes, items.cat.codes)))
    matrix = coo.tocsr()
    matrix.data = matrix.data.clip(min=0)
    matrix.eliminate_zeros()
    return _drop_empty(matrix, users.cat.categories, items.cat.categories)
The clip and eliminate_zeros are the second line of defence: a route whose every sale was cancelled becomes an all-zero column, and an all-zero column is still an item the model can rank and recommend.
Two bugs that never raised an error
I built a hybrid model with LightFM, engineering route features: popularity, one-hot class encodings, and temporal features including Hijri-calendar seasonality, because Ramadan and both Eids drive Moroccan travel demand and shift roughly 11 days earlier each Gregorian year. A model that only sees Gregorian dates cannot learn them as a recurring pattern.
Everything ran. Everything produced three plausible route IDs per traveller. Then I measured held-out AUC: pure collaborative filtering scored 0.976, and the hybrid scored 0.126. A score of 0.126 doesn’t mean the model was weak — it means it was actively anti-correlated, systematically ranking the worst routes first, silently, while returning perfectly well-formed output.
There were two independent causes. The first: LightFM replaces item identity with the features you supply rather than adding to it. Passing 20 content columns for 1,736 routes collapses every route sharing a class onto a single embedding. Counting distinct top-3 recommendation sets across 30 users made it unambiguous.
- No features, pure collaborative filtering: 22 distinct sets
- Content only: 3 — exactly the number of content classes
- Identity plus content: 21
The second: a raw count mixed in with 0/1 indicators. My popularity feature ranged from 1 to 101,245 alongside one-hot columns of magnitude 0 to 1, and it dominated every gradient update. Fixed with log1p plus max-scaling, placed inside the feature builder so the module’s output is safe by default instead of depending on the caller remembering.
What makes this one uncomfortable is that an earlier draft of my own documentation listed the unscaled feature as a known limitation — “would need scaling before use” — without recognising that it was, at that exact moment, destroying the model.
“A broken recommender doesn’t crash. It returns three plausible IDs. Only a quantitative metric on held-out data distinguishes a model that works from one that merely produces well-formed output.”
The evaluation protocol changed the conclusion
With both bugs fixed the hybrid scored 0.972 against pure CF’s 0.976 — matching, not beating. That is a finding about the data: the available content features carried no signal the interaction matrix didn’t already hold.
But a random 80/20 split is a forgiving benchmark, because the held-out fifth shares users, routes and time period with the training set, so a model can succeed by recognising rather than generalising. So I trained on the 2017–2020 file and evaluated on 2021–2022. Only 18.4% of evaluation clients had been seen in training, while 99.8% of routes carried over — the network is stable, the customer base isn’t. Excluding 19,423 repeat purchases already present in training left 44,644 genuinely new interactions.
The verdict hardened: pure CF scored 0.8996, and every hybrid configuration landed between 0.8752 and 0.8842. A feature derived from one window’s snapshot, such as a popularity count or a peak-hour share, describes when it was measured, not a stable property of the route.
Then the hyperparameter sweep found something bigger than any feature choice. With WARP loss, AUC decreased monotonically with training time — 0.9665 at 5 epochs, 0.9655 at 10, 0.9646 at 15, 0.9640 at 20, 0.9634 at 25, 0.9629 at 30. The default I had been using, 20 epochs, was already well past optimum. Retuning to 5 epochs and 64 components raised cross-window AUC from 0.8996 to 0.9225, a larger gain than every feature I engineered, combined.
The honest conclusion, and not the one I expected going in: the right configuration was a well-tuned plain collaborative filter, not a hybrid. The hybrid capability is wired, tested and evaluated. It just runs with content features switched off, because that is what the evidence supports.
Shipping it
A model that only runs in a notebook has no operational value. The final piece was a FastAPI service exposing the recommendation path, with a web interface in plain HTML and CSS matching the operator’s own visual identity, 76 automated tests, and CI.
One design decision was worth measuring. The implicit library excludes already-consumed items by default: it answers “routes this traveller has never tried”. But the product goal is “the trip this traveller will actually take”, which for a commuter is precisely their usual line. Inverting the default, measured across 300 established travellers:
- Their most frequent route appears in the top 3: 0% → 67.7%
- Recommended routes they already travel: 0% → 78.0%
The zeros are zero by construction. The change also fixed a silent divergence: LightFM never filtered, ALS always did, so the two endpoints had been answering different questions.
Serving a model is a concurrency problem too. Wiring the UI to issue two parallel requests surfaced two defects that would hit any real concurrent traffic. A pandas Index builds its hash engine lazily and not thread-safely, so two threads racing to initialise it throw a KeyError on an ID that exists. And this one was mine — a memoisation cache published its validity sentinel before the value.
# Wrong: another thread sees a "valid" cache and reads a key that isn't there yet.
if _state.get("volumes_source") is not matrix:
    _state["volumes_source"] = matrix
    _state["item_volumes"] = expensive_computation(matrix)
return _state["item_volumes"]
Compute first, publish the value, publish the sentinel last, and return the local variable rather than re-reading shared state. Sixty concurrent requests against a cold service now all succeed; before the fix, several didn’t.
And the CI had never run. The workflow triggered on main while the repository’s default branch was master. Zero runs, ever, which is why a missing test dependency had gone undetected for weeks. Worth checking on your own repos.
What I actually took away
- A broken model doesn’t announce itself. I no longer treat plausible output as evidence that anything works.
- The evaluation protocol determines the conclusion. A random split said the model was fine; a cross-window split revealed overfitting the first had completely masked.
- A documented negative result has real value. My starting hypothesis was refuted on two independent protocols, and writing that up tells the warehouse team exactly what to provide next.
- Qualifying data beats accumulating it. The cold-start rate rose from 71.6% to 76.5% when a third file was added, and understanding why was worth more than the extra rows.
Built with Python, pandas, SciPy, implicit, LightFM, Parquet, FastAPI and pytest, at ONCF, Direction des Systèmes d’Information et Digital, Rabat, July to September 2026.