Abdelhamid SAIDI
About Me
As a Software Engineering student @FST Settat with a strong passion for data engineering and analytics, I enjoy designing and working with databases, building pipelines, and exploring data to extract meaningful insights.
I have worked on projects ranging from data warehousing and analytics to cloud-based solutions. My focus is on applying modern tools and best practices to create scalable, efficient, and insightful data solutions.
If you find my profile interesting, let's connect! I'm always open to exchanging ideas, collaborating, and learning from others in the data field.
Experience
DataOps Intern
Built and operated a real-time security log pipeline (Kafka, Flink, ClickHouse, Airflow) on Kubernetes, with GitHub Actions CI/CD, operator-based autoscaling, Prometheus/Grafana monitoring and alerting, secrets management via mounted files, and an automated MLOps loop with gated model promotion and rollback, processing 5200 events/s at a median 194 ms end-to-end latency.
Data Science Intern
Architected a hybrid recommendation engine for ONCF on real rail ticket-sales records, combining a personalized collaborative-filtering model with a popularity-based cold-start strategy covering 76% of travellers. Benchmarked and tuned two algorithms to work together in order to deliver better results, lifting AUC to 0.92. Delivered end-to-end with 76 automated tests and CI.
Data Engineering Intern
PMapping: Delivery Provider Mapping & Rating
A six-stage pipeline turning the agency listings of four Moroccan carriers into a branch-level rating database — 409 listings across 13 cities, enriched via the Google Places API with a Playwright fallback and a name-match guard against wrong records.
Morocco B2B Market Supplier Discovery Pipeline
An Airflow-orchestrated pipeline collecting and qualifying over 30,000 supplier records from two Moroccan B2B directories. Collection is idempotent and parallelised per source; records are enriched via Google Maps, then deduplicated across sources.
Data Engineering Intern
Built a unified administrative database by integrating and harmonizing data from multiple government systems, implemented Python-based deduplication and normalization to ensure clean, unique, and searchable records, and optimized relational database indexing, data structures, interoperability, and overall data consistency.
Technical Skills
Programming Languages


Data Engineering & Architecture


Big Data & Analytics Platforms


Databases & Data Engineering


Orchestration, DataOps & Workflow


Data Visualization & Reporting


Certifications & Credentials


Education
Engineer's degree in Computer Engineering
Engineering studies with focus on Computer Science and Software Development
Physics & Engineering Sciences
Intensive preparatory program focused on mathematics, physics, and engineering fundamentals.
Featured Projects
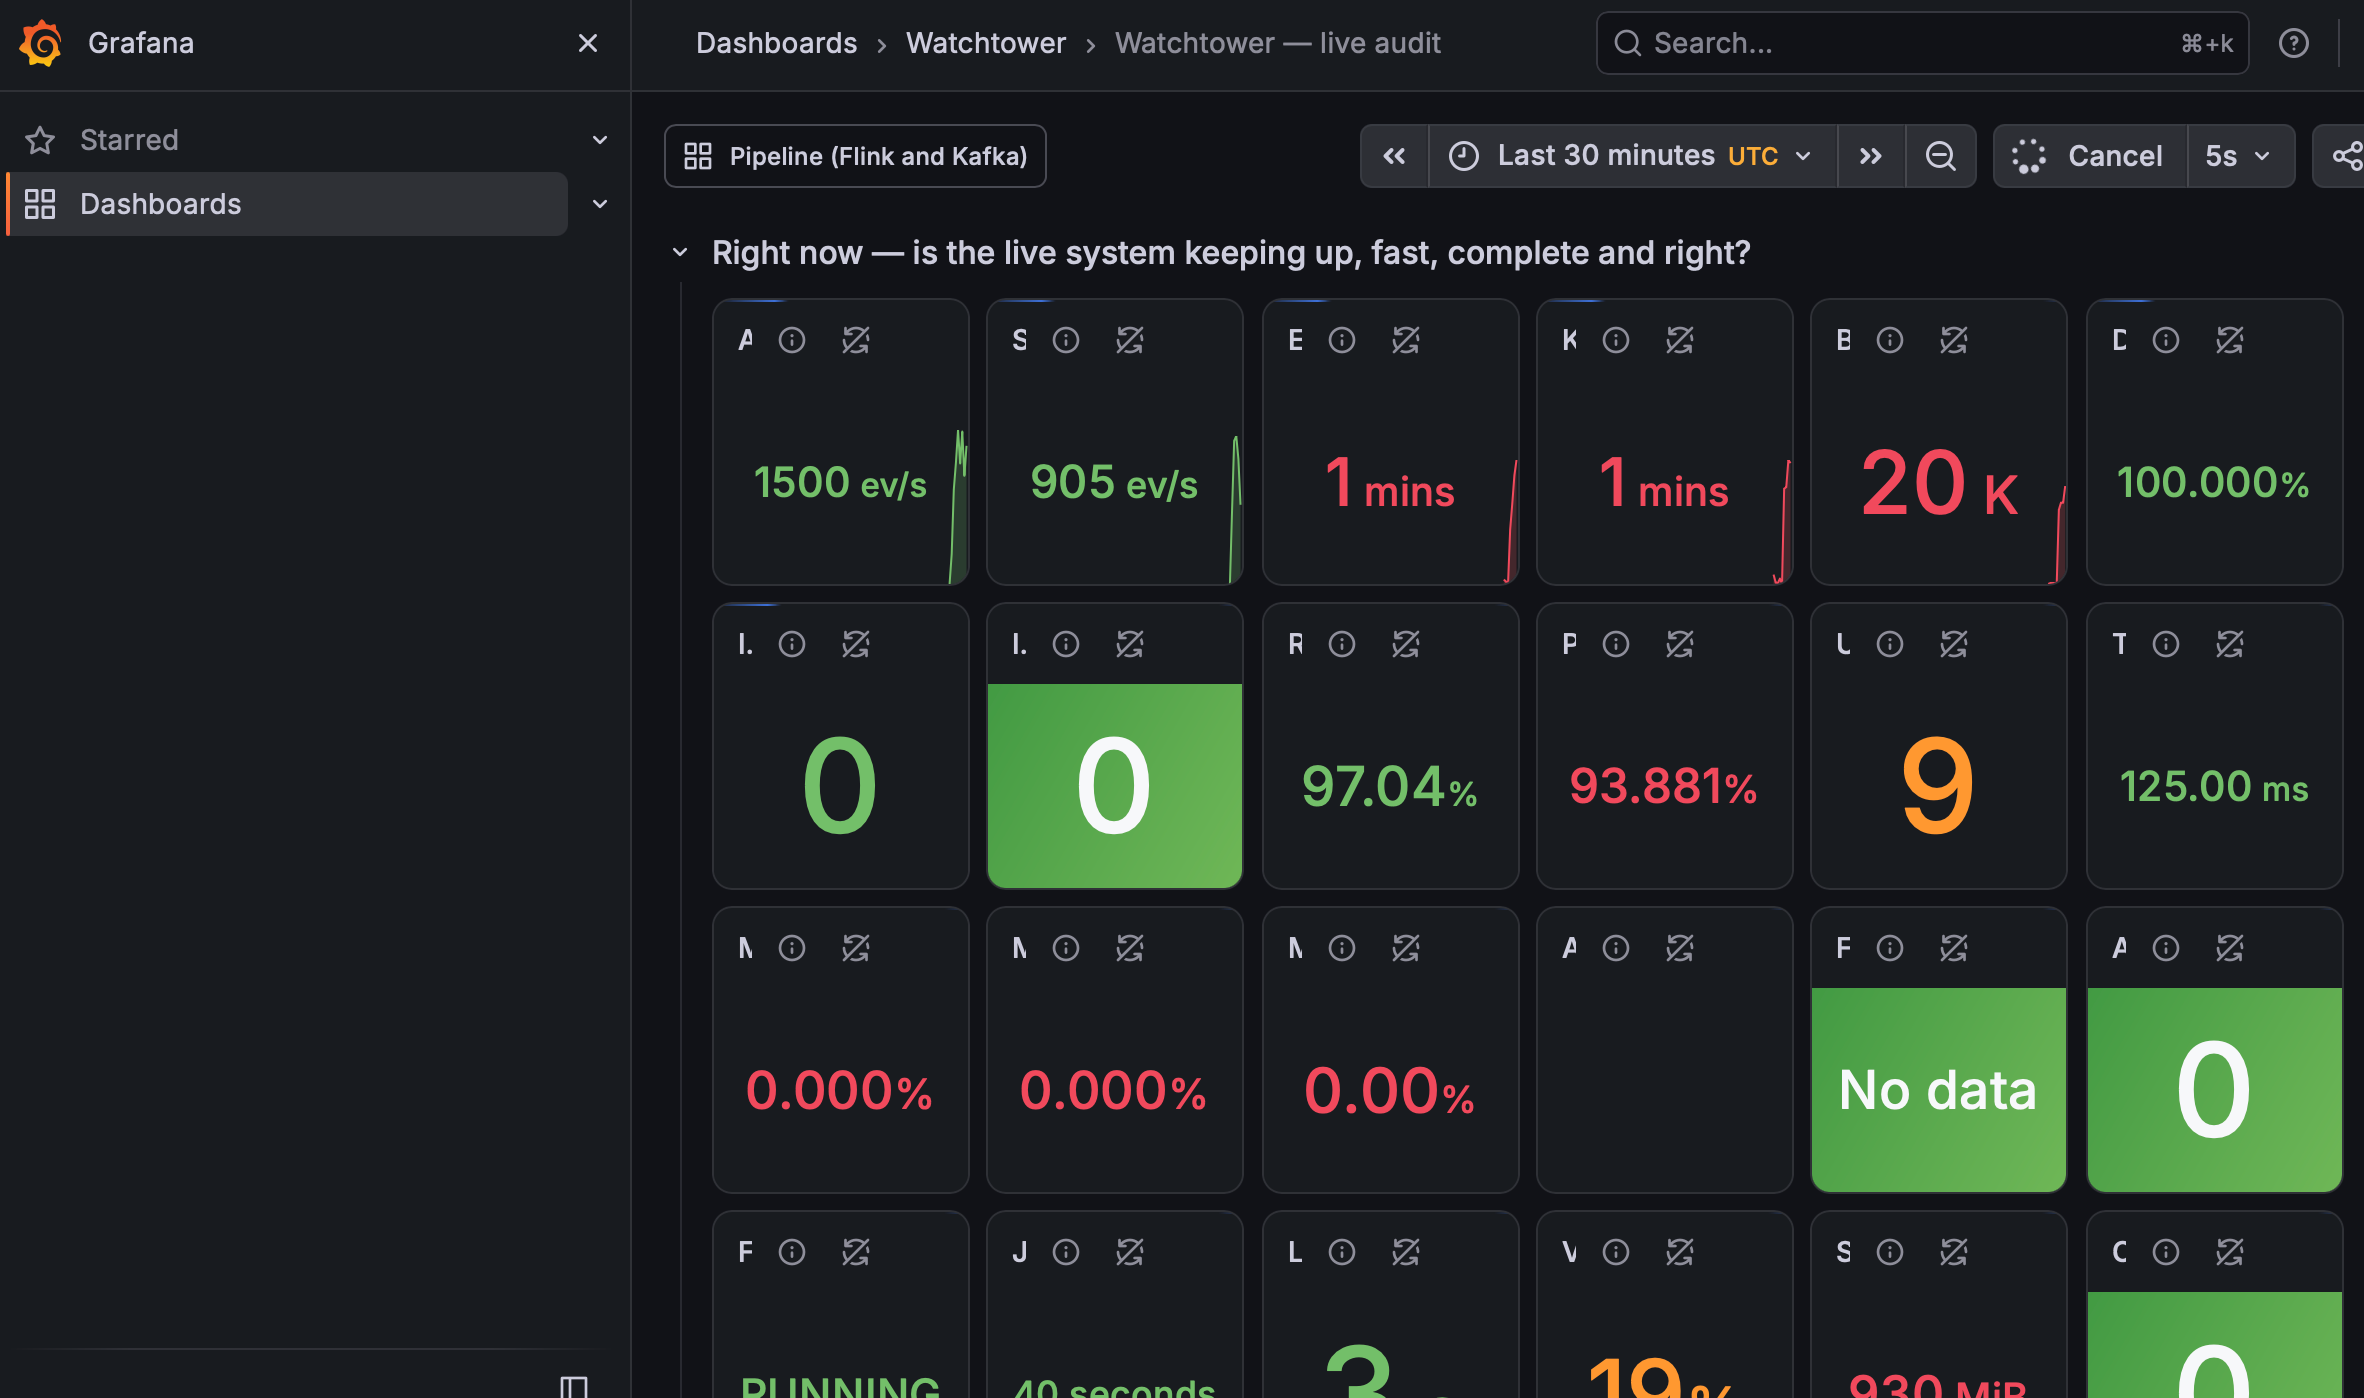
Real-time log pipeline for a build farm. Streams logs through Kafka and Flink into ClickHouse, with Airflow orchestration and LLM-based anomaly classification.
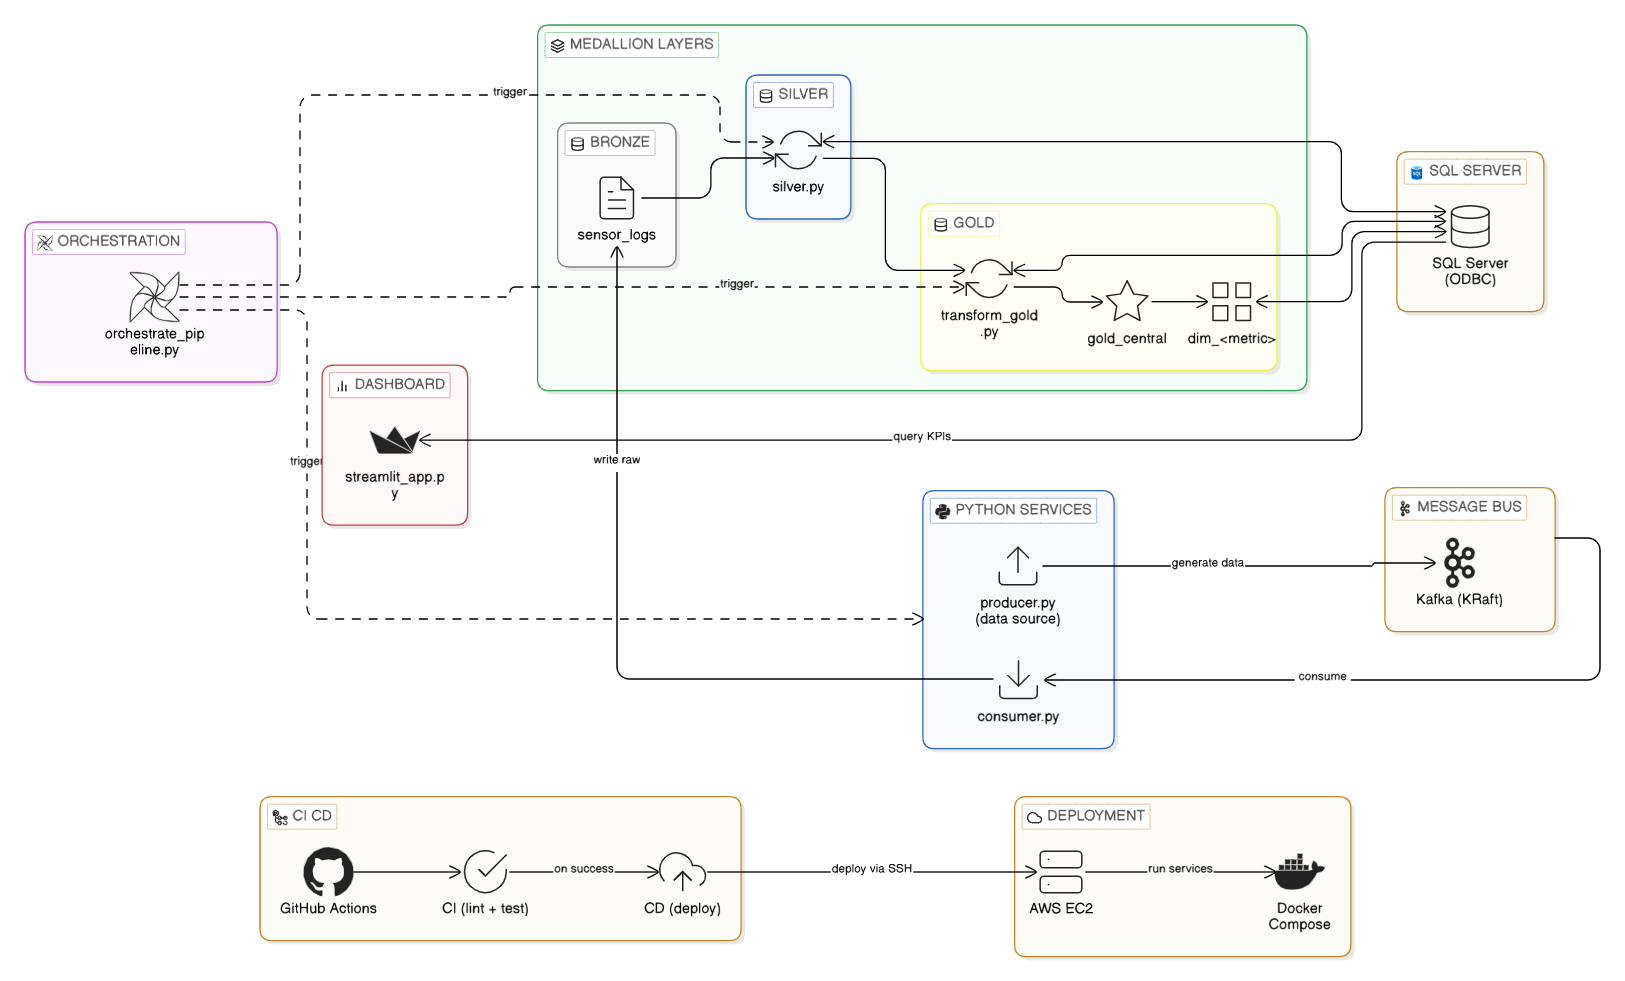
End-to-end streaming pipeline for IoT sensor data. Includes Docker/Docker Compose setup for local development.
End-to-end ELT pipeline extracting TPCH orders into Snowflake and transforming with dbt, orchestrated by Apache Airflow.
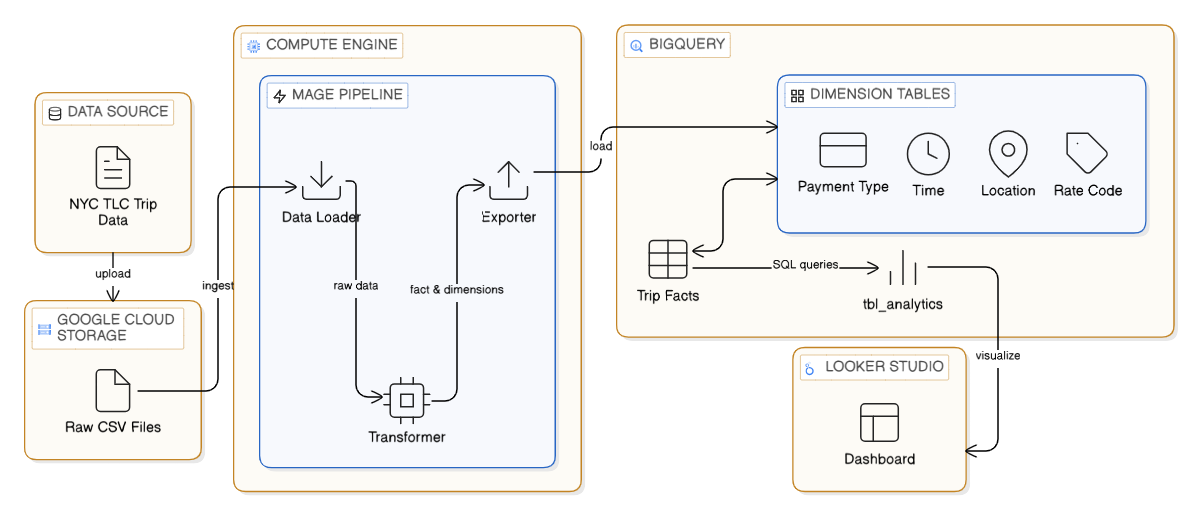
Built an end-to-end GCP pipeline with Mage, BigQuery, and Looker Studio for automated data ingestion and real-time analytics.
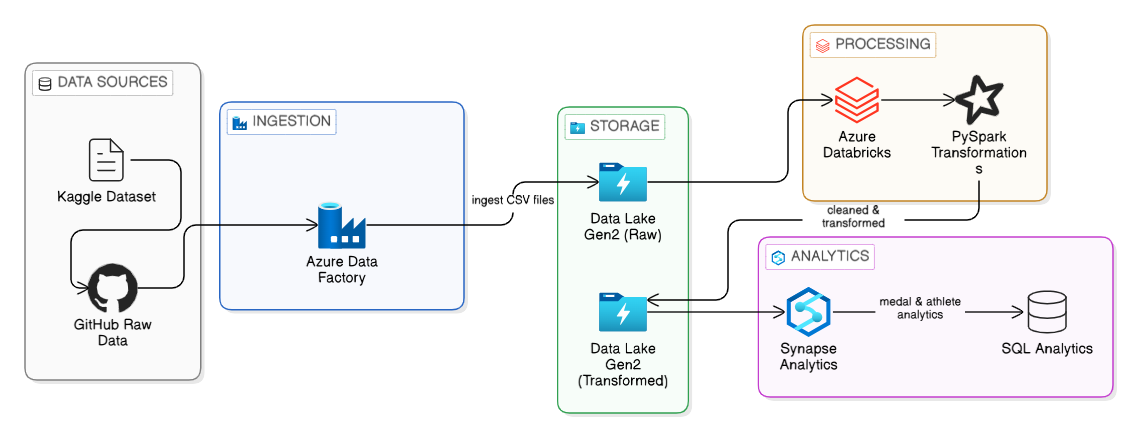
End-to-end Azure ETL and analytics pipeline processing Tokyo 2020 Olympics data using Data Factory, Databricks, and Synapse.
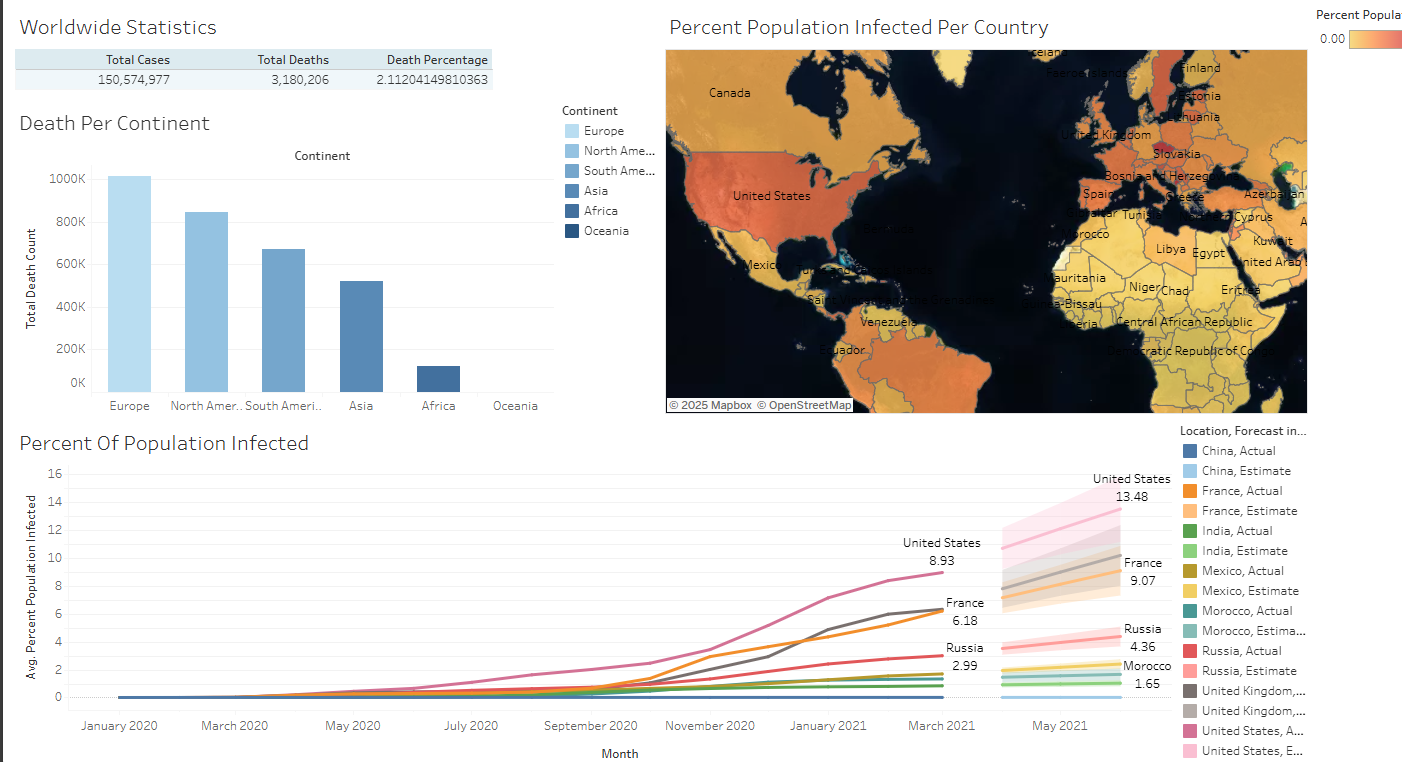
Comprehensive exploration of global COVID-19 data (2020–2021) with SQL analytics and Tableau dashboards highlighting key pandemic patterns.